Neutron Controller Events
Reference documentation for the Kubernetes events the two Neutron controllers emit. They make a failed migration Job, a refused release transition and a failed OVN comparison visible through kubectl describe neutron and kubectl get events without reading controller logs.
Events complement status conditions. A condition reports current state for programmatic consumers; an event is a timestamped record of a transition, which is what an operator reads after the fact and what an alerting rule matches on. For the conditions themselves see Neutron CRD and NeutronMetadataAgent CRD; for the pipelines that set them, Reconciler Architecture.
Event Conventions
- Reason strings are stable PascalCase identifiers. They are part of the controllers' public API and will not change without a deprecation notice.
- Normal marks the successful completion of a lifecycle transition, Warning a failure, a refused transition or a degradation that needs attention.
- No event is emitted for an in-progress or polling state, so a requeue cycle produces no event noise.
DBSyncInProgress,ExpandInProgressand their siblings are condition reasons only. - An event on a
Neutron(involvedObject.kind: Neutron) carries the recorder nameneutron-controller, and one on aNeutronMetadataAgentcarriesneutronmetadataagent-controller. That is what thereportingComponentfield selector matches. Both recorders are wired inoperators/neutron/main.go. - The API server deduplicates events by (involvedObject, reason, message, source). Repeated identical events increment a counter rather than creating new objects.
Event Reasons Reference
Configuration
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
ExtraConfigOwnedKeyOverride | Warning | spec.extraConfig overrides one or more operator-owned configuration keys of the kind's ownership registry | spec.extraConfig overrides operator-owned keys: [ovn] ovn_l3_scheduler |
Source: the shared RecordExtraConfigHealth in internal/common/config/ownership.go, called from reconcileConfig in reconcile_config.go for a Neutron and from reconcileAgentConfig in reconcile_agent_config.go for a NeutronMetadataAgent
Note: The event is gated on the
ExtraConfigHealthy=Falsecondition's message. It fires once on the transition intoFalseand once more when the overridden-key set changes, never on the steady reconcile poll. Removing the overrides transitions the condition back toExtraConfigHealthy=True, Reason=NoOwnedKeysOverriddenwithout a further event. The condition is informational and is not aggregated intoReady. The keys the validating webhook refuses at admission (fourteen onNeutron, six onNeutronMetadataAgent) never reach this path.
Database Sync
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
DatabaseSynced | Normal | The {name}-db-sync Job completes successfully | Database schema is up to date |
DBSyncFailed | Warning | The {name}-db-sync Job fails | db_sync job failed: <error> |
DBSyncMetricEmissionDeferred | Warning | Patching the last-observed Job UID annotation onto the Neutron fails, deferring the db_sync metrics to the next reconcile | Patching last-observed db-expand Job UID failed; metric emission deferred to the next reconcile: <error> |
Source: the shared ReconcileSyncJobs in internal/common/database/flow.go (DatabaseSynced / DBSyncFailed); the shared RecordJobTerminalState in internal/common/job/terminal.go, wired through recordDBJobTerminalState in db_job_metrics.go (DBSyncMetricEmissionDeferred)
One deferral reason covers four Jobs. The %s in the message is the phase suffix the metrics are keyed on, so it reads db-sync in steady state and db-expand, db-migrate or db-contract during a release upgrade.
Release Transitions
The release gate validates a spec.openStackRelease change against status.installedRelease before the upgrade flow is entered. A refused transition sets DatabaseReady=False, raises one Warning event whose reason names the rule that refused it, and returns an error so the controller backs off.
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
VersionParseError | Warning | The installed or the requested release is not a valid YYYY.N string | parsing requested release "latest": invalid release format "latest": expected YYYY.N |
DowngradeNotSupported | Warning | The requested release is older than the installed one | downgrade from 2026.2 to 2026.1 is not supported |
UpgradePathInvalid | Warning | The requested jump is more than one release | upgrade from 2024.2 to 2026.1 is not sequential; upgrade one release at a time |
ImageReleaseMismatch | Warning | The requested release bump leaves spec.image at the reference that migrated the installed schema, so no migration would run | see the message below |
Source: gateReleaseTransition and rejectReleaseTransition in reconcile_database.go
The gate runs ahead of the upgrade flow, so the wording an operator sees for the first three reasons is the gate's. The shared InitiateUpgrade carries the same three reasons with capitalised wording of its own, behind that gate.
ImageReleaseMismatch names both readings of the state it refuses, because only the operator knows which one applies and the recovery differs:
upgrade from %s to %s leaves spec.image unchanged (%s), so no migration would run: either bump spec.image in lockstep with spec.openStackRelease, or — if that image already migrated the schema on an earlier pass, because its digest was bumped before spec.openStackRelease was — patch status.installedRelease to %s to record the migration that has already runNote:
ImageReleaseMismatchhas a second trigger that raises no event. When a tag-pinnedspec.imagenames a different OpenStack release thanspec.openStackRelease,checkImageReleaseMismatchsetsDatabaseReady=Falsewith that reason and requeues without recording anything, because the check runs on every pass and would otherwise re-fire for as long as the two fields disagree. Read that case off the condition, not the event stream.
Upgrade
An accepted release bump walks the shared expand-migrate-contract flow. Neutron runs the full phase machine: its alembic tree splits into an expand and a contract branch, and status.upgradePhase reports where a bump has got to.
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
UpgradeInitiated | Normal | An accepted release bump starts the upgrade | Upgrade initiated: 2026.1 → 2026.2 |
ExpandComplete | Normal | The {name}-db-expand Job succeeded | Expand phase complete: 2026.1 → 2026.2 |
MigrateComplete | Normal | The {name}-db-migrate Job succeeded | Migrate phase complete: 2026.1 → 2026.2 |
DeploymentRolloutComplete | Normal | The API Deployment rolled out onto the target-release image; the phase flips to Contracting | Deployment rollout complete during upgrade 2026.1 → 2026.2 |
UpgradeComplete | Normal | The {name}-db-contract Job succeeded; the upgrade finished | Upgrade complete: 2026.1 → 2026.2 |
UpgradeAborted | Normal | spec.openStackRelease reverted to the installed release, cancelling the upgrade and deleting the three phase Jobs | Upgrade 2026.1 → 2026.2 aborted: spec release reverted to installed release 2026.1 |
UpgradeTargetChanged | Warning | spec.openStackRelease changed to a third value during an active upgrade | Spec release changed to 2027.1 during active upgrade 2026.1 → 2026.2 |
ExpandFailed | Warning | The expand phase Job failed permanently | Expand job neutron-db-expand failed: <error> |
MigrateFailed | Warning | The migrate phase Job failed permanently | Migrate job neutron-db-migrate failed: <error> |
ContractFailed | Warning | The contract phase Job failed permanently | Contract job neutron-db-contract failed: <error> |
VersionParseError, DowngradeNotSupported, UpgradePathInvalid | Warning | The same three rules, re-checked inside InitiateUpgrade | Downgrade from 2026.2 to 2026.1 is not supported |
Source: the shared expand-migrate-contract flow in internal/common/database/upgrade.go, wired through upgradeFlowParams in reconcile_database.go and CompleteRollingUpdate in reconcile_deployment.go
The migrate phase runs neutron-db-manage current. Neutron's alembic tree has no data-migration command between expand and contract, and printing the revision each branch sits at keeps the phase readable in the Job log.
OVN Schema Sync
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
OVNDBSyncJobFailed | Warning | The newest terminal run of the {name}-ovn-db-sync CronJob failed | see the template below |
OVNDBSyncMetricEmissionDeferred | Warning | Patching the last-observed Job UID annotation onto the Neutron failed, so the OVN sync metrics are deferred to the next reconcile | Patching last-observed ovn-db-sync Job UID failed; metric emission deferred to the next reconcile: <error> |
Source: reconcileOVNDBSync in reconcile_ovndbsync.go; the second reason is the deferral reason its RecordJobTerminalState call passes
OVN database synchronisation Job %s failed; inspect its pod logs. A "Could not retrieve schema from <address>" line means the Northbound database was unreachable rather than out of stepThat line is the one distinction the log carries. log mode exits 0 whether or not the two databases agree, so a non-zero exit is an unreachable Northbound or a broken run, never drift.
OVNDBSyncJobFailed is also the reason of the OVNDBSyncReady=False condition, and the two fire on different schedules. The condition is set on every pass for as long as the failed Job stays the newest terminal one; the event rides the terminal-state helper, which dedupes on the Job UID through an annotation on the CR, so it fires once per failed run.
Finalization
Emitted while the finalizers tear a deleted Neutron down. FinalizingDatabase is gated on live MariaDB cleanup work remaining, so brownfield CRs (no MariaDB CRs) and repeated requeue polls produce no noise.
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
FinalizingDatabase | Normal | Deletion begins while MariaDB Database/User/Grant CRs are still live | Cleaning up MariaDB Database, User, and Grant before removing Neutron |
DatabaseFinalized | Normal | MariaDB resources marked for deletion; finalizer released | MariaDB Database, User, and Grant marked for deletion; releasing finalizer |
RemoteChildrenAbandoned | Warning | Deletion begins while the target cluster the CR named no longer resolves; the finalizer is released without touching what was written there | Target cluster is no longer registered; releasing the finalizer without deleting the MariaDB Database, User, and Grant on it |
Source: reconcileDelete in neutron_controller.go
A placed Neutron carries a second finalizer for the children on the target cluster, and its sweep raises RemoteChildrenAbandoned under a message of its own:
Target cluster is no longer registered; releasing the remote-children finalizer without deleting the objects on it labelled as owned by this NeutronSource: SweepRemoteChildren in internal/common/multicluster/teardown.go, called from reconcileDeleteRemoteChildren in both controllers
Before the abandon window expires the deletion requeues instead, and the wait is reported with reason TargetClusterUnavailable on the first condition of the CR's pipeline: SecretsReady=False on a Neutron, ChassisReady=False on a NeutronMetadataAgent. Engagement of a target cluster is asynchronous, so an operator restart looks like a deregistration until the provider has synced.
Metadata Agent Controller
neutronmetadataagent-controller records three reasons. The first two are shared with the Neutron controller and listed above:
| Reason | Type | Trigger Condition | Example Message |
|---|---|---|---|
ExtraConfigOwnedKeyOverride | Warning | spec.extraConfig overrides one or more keys of MetadataAgentOwnedConfigKeys | spec.extraConfig overrides operator-owned keys: [oslo_concurrency] lock_path (the operator mounts a writable volume at this path; another path names a directory the container cannot write) |
RemoteChildrenAbandoned | Warning | A placed agent is deleted while its target cluster no longer resolves | Target cluster is no longer registered; releasing the remote-children finalizer without deleting the objects on it labelled as owned by this NeutronMetadataAgent |
MetadataSharedSecretMirrorReaped | Normal | A placed agent is deleted and no other live agent in its namespace on its cluster names a metadata shared-secret copy the ControlPlane delivered there. One event per deleted copy | Deleted the metadata shared-secret mirror controlplane-nova-metadata-agent-secret: no other NeutronMetadataAgent on this cluster names it |
Nothing else in that pipeline raises an event. The chassis, the credentials and the DaemonSet all report through their conditions, since each of their states is one to wait out and retry; none of them is a transition worth an audit record.
Reasons that never fire for Neutron
| Reason | Why it cannot occur |
|---|---|
SchemaDriftDetected | The Job set carries no schema-check command (SchemaCheckCommand: nil). neutron-db-manage upgrade head applies every pending revision of both branches in one idempotent pass, so a second read-only Job would assert nothing |
DBSyncInProgress, ExpandInProgress, MigrateInProgress, ContractInProgress, UpgradeRollingUpdate | DatabaseReady=False condition reasons while a Job or a rollout runs, never events: the polling states raise none |
Every reason of ChassisReady, OVNEndpointsReady, DeploymentReady, WorkersReady, NeutronAPIReady, HTTPRouteReady, HPAReady and NetworkPolicyReady | These steps report on their conditions alone. Read the current state there |
Alerting Configuration
Event reason strings are designed to be stable identifiers for alerting rules. Use kubectl get events --field-selector to filter by reason:
# Watch for db-sync failures
kubectl get events --field-selector reason=DBSyncFailed -w

# Watch for a rejected release upgrade path
kubectl get events --field-selector reason=UpgradePathInvalid -w

# Watch for a failed comparison against the OVN Northbound database
kubectl get events --field-selector reason=OVNDBSyncJobFailed -w

# Watch for an extraConfig override of an operator-owned key
kubectl get events --field-selector reason=ExtraConfigOwnedKeyOverride -w

# Watch for children left behind on a deregistered target cluster
kubectl get events --field-selector reason=RemoteChildrenAbandoned -w

# Watch for all Warning events from either controller
kubectl get events --field-selector type=Warning,reportingComponent=neutron-controller -w
kubectl get events --field-selector type=Warning,reportingComponent=neutronmetadataagent-controller -w
Prometheus Alertmanager Example
When using kube-state-metrics with event metrics enabled, you can alert on specific event reasons:
groups:
  - name: neutron-events
    rules:
      - alert: NeutronDBSyncFailed
        expr: |
          increase(kube_event_count{
            reason="DBSyncFailed",
            involved_object_kind="Neutron"
          }[5m]) > 0
        for: 0m
        labels:
          severity: critical
        annotations:
          summary: "Neutron db-sync failed"
          description: "The Neutron db-sync Job has failed. Check the Job logs for details."
A failed OVN comparison also moves neutron_operator_ovn_db_sync_total{result="failed"}, which is the signal to alert on where the event stream is not collected.
Event Flow
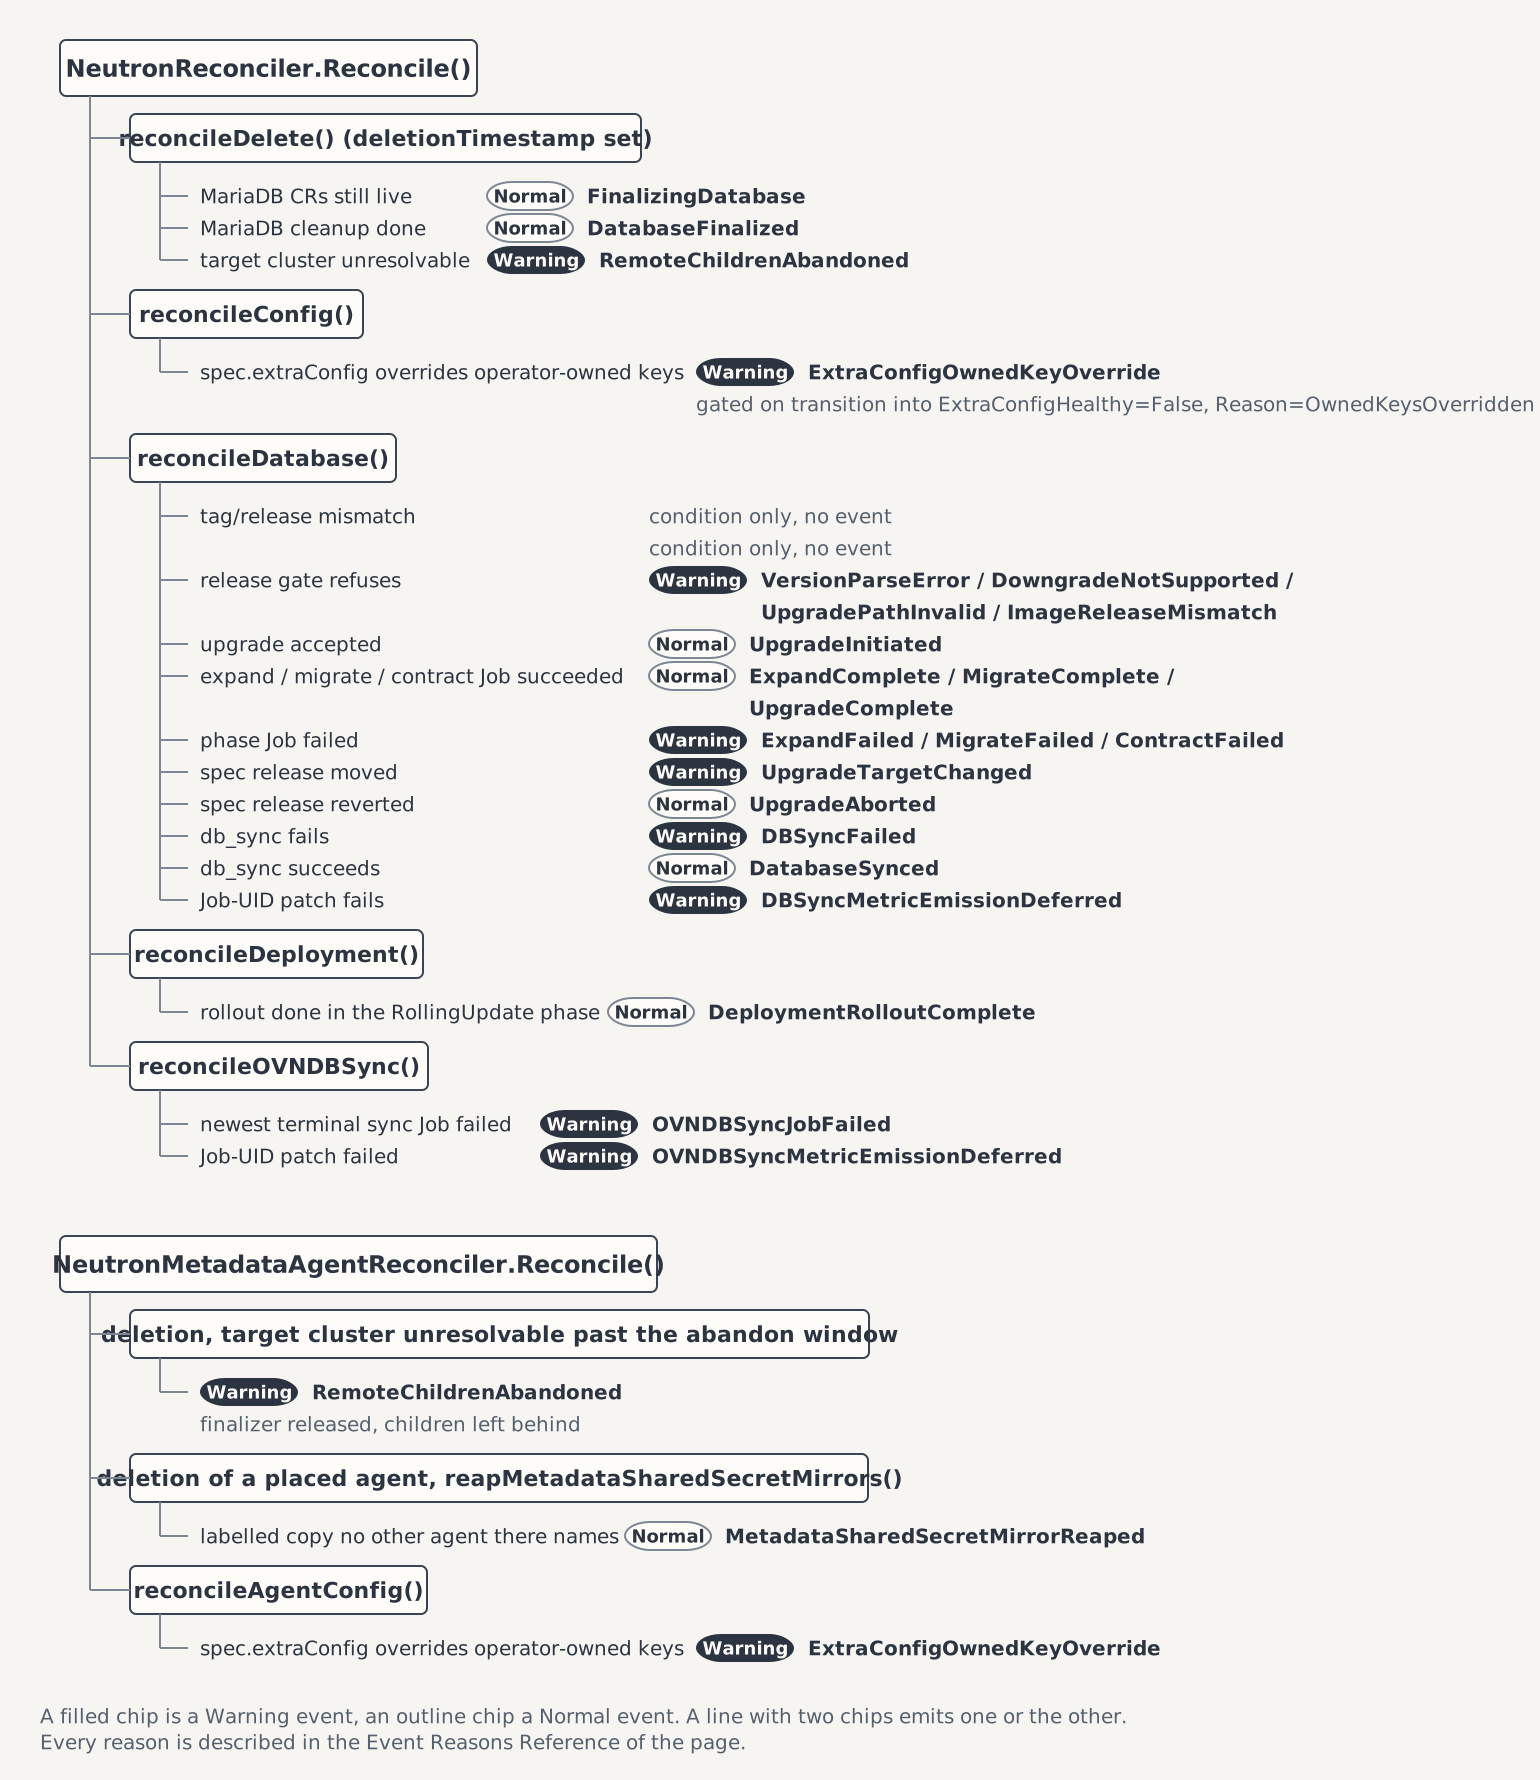
The figure draws which sub-reconciler emits which event, and on what. The Event Reasons Reference describes every reason.