Nova Controller Events
Reference documentation for the Kubernetes events the Nova and NovaCompute controllers emit. The events make the lifecycle transitions readable through kubectl describe nova, kubectl describe novacompute and kubectl get events, without access to the controller logs.
Events complement the status conditions: a condition reflects current state for programmatic consumers, while an event is a timestamped record of a transition for human operators and alerting systems.
For the reconciler architecture and the sub-reconciler contracts, see Nova Reconciler Architecture.
Event conventions
All events follow these conventions:
- Reason strings are stable PascalCase identifiers. They are part of the controller's public API and will not change without a deprecation notice.
- Normal type indicates successful completion of a lifecycle transition.
- Warning type indicates a failure, a validation error, or a condition that requires operator attention.
- No events are emitted for in-progress or polling states, such as a
db-syncJob that is still running. This keeps repeated requeue cycles from producing event noise. - An event lands on the CR its controller reconciles: the Nova CR (
involvedObject.kind: Nova, reporting componentnova-controller) or a NovaCompute CR (involvedObject.kind: NovaCompute, reporting componentnovacompute-controller). - The Kubernetes API server deduplicates events by (involvedObject, reason, message, source). Repeated identical events increment a counter rather than creating new event objects.
Event reasons
Configuration
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
ExtraConfigOwnedKeyOverride | Warning | spec.extraConfig overrides one or more operator-owned configuration keys (the per-service ownership registry) | spec.extraConfig overrides operator-owned keys: [scheduler] discover_hosts_in_cells_interval (the interval is what maps a newly registered compute node into a cell; without it a new hypervisor stays invisible to scheduling) |
Source: config.RecordExtraConfigHealth, called from reconcileConfig in reconcile_config.go
Note: The event is gated on the
ExtraConfigHealthy=Falsecondition's message. It fires once on the transition intoFalseand once more when the overridden-key set changes, never on the steady reconcile poll. Removing the overrides transitions the condition back toExtraConfigHealthy=True, Reason=NoOwnedKeysOverriddenwithout a further event. The condition is informational and is not aggregated intoReady. The keys the webhook rejects outright never reach it; they are listed under extraConfig.
Database sync
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
DatabaseSynced | Normal | The db-sync Job completes successfully | Database schema is up to date |
DBSyncFailed | Warning | The db-sync Job fails | db_sync job failed: <error> |
DBSyncMetricEmissionDeferred | Warning | Patching the last-observed Job UID annotation fails, deferring the db_sync metric emission to the next reconcile | Patching last-observed db-sync Job UID failed; metric emission deferred to the next reconcile: <error> |
CellsReportUnavailable | Normal | The completed db-sync Job left no readable cell map in its pod's termination message | the db-sync Job reported no cell map; status.cells is left unchanged |
CellsReportEmissionDeferred | Warning | Patching the last-observed Job UID annotation fails, deferring the cell report to the next reconcile | Patching last-observed db-sync-cells Job UID failed; metric emission deferred to the next reconcile: <error> |
Source: the shared ReconcileSyncJobs in internal/common/database/flow.go (DatabaseSynced / DBSyncFailed); recordDBJobTerminalState in db_job_metrics.go (DBSyncMetricEmissionDeferred); reportCells in reconcile_database.go (CellsReportUnavailable / CellsReportEmissionDeferred)
Note: Nova runs a single
db-syncJob that migrates both schemas and maps the cells, with no separate schema-check Job, soSchemaDriftDetectednever fires for Nova.CellsReportUnavailableis Normal, not Warning: the cells are mapped either way, and the report only carries the UUIDs nova generated. A pass that cannot read them leavesstatus.cellsas it is, because dropping a published UUID would be worse than reporting a stale one.
Database archive
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
DBArchiveJobFailed | Warning | The newest terminal Job spawned by the {name}-db-archive CronJob failed | Database archive Job nova-db-archive-29387520 failed; inspect its pod logs. The soft-deleted instance rows keep accumulating in the live tables until a run succeeds |
DBArchiveMetricEmissionDeferred | Warning | Patching the last-observed Job UID annotation fails, deferring the db_archive metric emission to the next reconcile | Patching last-observed db-archive Job UID failed; metric emission deferred to the next reconcile: <error> |
Source: reconcileDBArchive in reconcile_dbarchive.go (DBArchiveJobFailed); the shared RecordJobTerminalState in internal/common/job/terminal.go (DBArchiveMetricEmissionDeferred)
Note: There is no Normal event for a successful archive run; a succeeding run only flips
DBArchiveReadyback toTrue. A run that wedges instead of failing reaches a terminalFailedstate through the Job'sactiveDeadlineSecondswithin the hour, so it surfaces on the same path.spec.dbArchive.suspendpauses the CronJob without deleting it and raises no event: a suspended archive is visible only through theDBArchiveSuspendedcondition reason.
Upgrade
A release transition (a spec.openStackRelease bump with the image in lockstep) walks the shared expand-migrate-contract flow, which emits these events on the Nova CR. For the phase machine see Release upgrade.
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
UpgradeInitiated | Normal | An accepted release bump starts the upgrade | Upgrade initiated: 2026.1 to 2026.2 |
ExpandComplete | Normal | The expand phase Job succeeded | Expand phase complete: 2026.1 to 2026.2 |
UpgradeCheckCompleted | Normal | The expand phase's nova-status upgrade check exited 0, or its exit code could not be read off the pod | nova-status upgrade check exit 0 |
UpgradeCheckWarnings | Warning | The same check reported anything but exit 0. Exit 1 carries warnings a deployment keeps, because the checks report on integrations it may not run; exit 2 and above also fail the phase Job | nova-status upgrade check exit 1 |
MigrateComplete | Normal | The migrate phase Job succeeded | Migrate phase complete: 2026.1 to 2026.2 |
DeploymentRolloutComplete | Normal | Every role finished rolling out the new image; the phase flips to Contracting | Deployment rollout complete during upgrade 2026.1 to 2026.2 |
UpgradeComplete | Normal | The contract phase Job succeeded; the upgrade finished | Upgrade complete: 2026.1 to 2026.2 |
UpgradeAborted | Normal | spec.openStackRelease reverted to the installed release, cancelling the upgrade | Upgrade 2026.1 to 2026.2 aborted: spec release reverted to installed release 2026.1 |
UpgradeCheckEventEmissionDeferred | Warning | Patching the last-observed Job UID annotation failed, deferring the upgrade-check report to the next reconcile | Patching last-observed db-expand-check Job UID failed; metric emission deferred to the next reconcile: <error> |
VersionParseError | Warning | The installed or target release is not a valid YYYY.N string | Failed to parse target release "latest": ... |
DowngradeNotSupported | Warning | The target release is older than the installed release | Downgrade from 2026.2 to 2026.1 is not supported |
UpgradePathInvalid | Warning | The requested jump is not a single sequential step | Upgrade from 2024.2 to 2026.1 is not sequential |
UpgradeTargetChanged | Warning | spec.openStackRelease changed to a third value during an active upgrade | Spec release changed to 2027.1 during active upgrade 2026.1 to 2026.2 |
ExpandFailed | Warning | The expand phase Job failed permanently | Expand job nova-db-expand failed: ... |
MigrateFailed | Warning | The migrate phase Job failed permanently | Migrate job nova-db-migrate failed: ... |
ContractFailed | Warning | The contract phase Job failed permanently | Contract job nova-db-contract failed: ... |
Source: the shared expand-migrate-contract flow in internal/common/database/upgrade.go; reportUpgradeCheck in reconcile_database.go for the two check events
Note: The upgrade check runs in the expand phase, ahead of the migrations it clears the way for, and its exit code is a severity rather than a success flag. The phase script normalises 0 and 1 to a zero exit and lets anything above 1 fail the Job, typically a cell mapping the
db-syncJob has not written yet. The real code travels in the pod's termination message, which is what the two events carry.
Finalization
Emitted while the finalizer tears a deleted Nova CR down. FinalizingDatabase is gated on live MariaDB cleanup work remaining, so brownfield CRs and repeated requeue polls produce no noise.
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
FinalizingDatabase | Normal | Deletion begins while the MariaDB Database/User/Grant CRs of either schema are still live | Cleaning up the MariaDB Databases, Users, and Grants of both schemas before removing Nova |
DatabaseFinalized | Normal | The MariaDB resources of both schemas are marked for deletion; the finalizer is released | MariaDB Databases, Users, and Grants marked for deletion; releasing finalizer |
RemoteChildrenAbandoned | Warning | Deletion begins while the target cluster the CR named no longer resolves; the finalizer is released without touching what was written there | Target cluster is no longer registered; releasing the finalizer without deleting the MariaDB Databases, Users, and Grants on it |
Source: reconcileDelete in nova_controller.go; the shared SweepRemoteChildren in internal/common/multicluster/teardown.go, which raises RemoteChildrenAbandoned once more for the label-selected children when the sweep cannot reach the cluster
NovaCompute
Emitted on a NovaCompute CR while it runs a node pool. For the pipeline see NovaCompute.
| Reason | Type | Trigger condition | Example message |
|---|---|---|---|
ComputeServiceDisabled | Normal | A node left the pool and its compute service was enabled; the pool disabled it once | Disabled the compute service of node node-1: it left the pool |
ComputeServiceDeleted | Normal | A released node's pod is gone and Nova deleted its compute service | Deleted the compute service of node node-1; Nova dropped its host mapping with it |
AggregateCreated | Normal | The pool created a host aggregate it needs | Created host aggregate az1 in availability zone az1 |
AggregateDeleted | Normal | A marked aggregate no pool of the Nova needs held no host and was deleted | Deleted host aggregate az1: no NovaCompute of Nova nova needs it |
AggregateKept | Warning | A marked aggregate no pool of the Nova needs held no host but carried metadata the operator did not set, so it was kept | Kept empty host aggregate az1: it carries metadata the operator did not set (filter_tenant_id) |
ComputeConfigMirrorReaped | Normal | The last pool of a Nova on a cluster deleted one of the ControlPlane's mirrors there, the compute contract or the hypervisor operator's auth Secret; one event per deleted Secret | Deleted the compute-contract mirror nova-compute-config: no other NovaCompute of Nova nova uses it on this cluster, Deleted the hypervisor-operator auth mirror nova-hypervisor-operator-auth: no other NovaCompute of Nova nova uses it on this cluster |
NodeConflict | Warning | A selected node is held by another NovaCompute of the same Nova; fires once per new conflict | Node node-1 is held by NovaCompute pool-a; this pool runs no pod on it |
HostDiscoveryStarted | Normal | A node's service is registered but its host is not mapped, and the pool created the Nova's host discovery Job | Started Job openstack/nova-discover-hosts to map node-1 into the cell |
HostDiscoveryFailed | Warning | The host discovery Job failed and the pool replaces it, 30 seconds after the failure; the message carries the Job's failed condition | Job openstack/nova-discover-hosts failed: Job has reached the specified backoff limit |
ExtraConfigOwnedKeyOverride | Warning | spec.extraConfig overrides a reported [libvirt] key | spec.extraConfig overrides operator-owned keys: [libvirt] virt_type |
Source: reconcileNovaComputeServices in reconcile_novacompute_services.go (ComputeServiceDisabled, ComputeServiceDeleted); reconcileNovaComputeAggregates in reconcile_novacompute_aggregates.go (AggregateCreated, AggregateDeleted, AggregateKept); reapComputeClusterMirrors in novacompute_controller.go (ComputeConfigMirrorReaped); reconcileNovaComputeNodes in reconcile_novacompute_nodes.go (NodeConflict); ensureHostDiscovery in reconcile_novacompute_hostdiscovery.go (HostDiscoveryStarted, HostDiscoveryFailed); config.RecordExtraConfigHealth, called from reconcileNovaComputeConfig (ExtraConfigOwnedKeyOverride)
Note: A NovaCompute on a deregistered target cluster raises
RemoteChildrenAbandonedfrom the shared sweep, as a Nova does.
Alerting
Event reason strings are stable identifiers for alerting rules. Use kubectl get events --field-selector to filter by reason:
# Watch for a failed database archive
kubectl get events --field-selector reason=DBArchiveJobFailed -w

# Watch for a failed db-sync
kubectl get events --field-selector reason=DBSyncFailed -w

# Watch for all Warning events from the nova-controller
kubectl get events --field-selector type=Warning,reportingComponent=nova-controller -w
The two recurring Jobs also feed per-CR Prometheus counters, which carry the terminal result as a label and outlive the events the API server prunes. The rules below alert on the failed result of each.
apiVersion: monitoring.coreos.com/v1
kind: PrometheusRule
metadata:
  name: nova-operator-jobs
  namespace: openstack
spec:
  groups:
    - name: nova-operator-jobs
      rules:
        - alert: NovaDBSyncFailed
          expr: |
            increase(nova_operator_db_sync_total{result="failed"}[15m]) > 0
          for: 0m
          labels:
            severity: critical
          annotations:
            summary: "Nova db-sync failed"
            description: "A Nova db-sync or upgrade-phase Job failed, so the schema is not at the release the operator was told to converge to. Check the Job logs."
            runbook_url: "https://github.com/C5C3/cobaltcore/blob/main/docs/reference/nova/nova-reconciler.md#database"

        - alert: NovaDBArchiveFailed
          expr: |
            increase(nova_operator_db_archive_total{result="failed"}[15m]) > 0
          for: 0m
          labels:
            severity: warning
          annotations:
            summary: "Nova database archive failed"
            description: "A Nova db-archive run failed. The soft-deleted instance rows keep accumulating in the live tables until a run succeeds; check the Job logs."
            runbook_url: "https://github.com/C5C3/cobaltcore/blob/main/docs/reference/nova/nova-reconciler.md#dbarchive"
Both counters are labelled by nova and namespace, so an alert names the CR it fired for. nova_operator_db_sync_total covers the steady-state db-sync and the three upgrade phases alike: they share the collector and differ in the Job the terminal state was read off.
Event flow
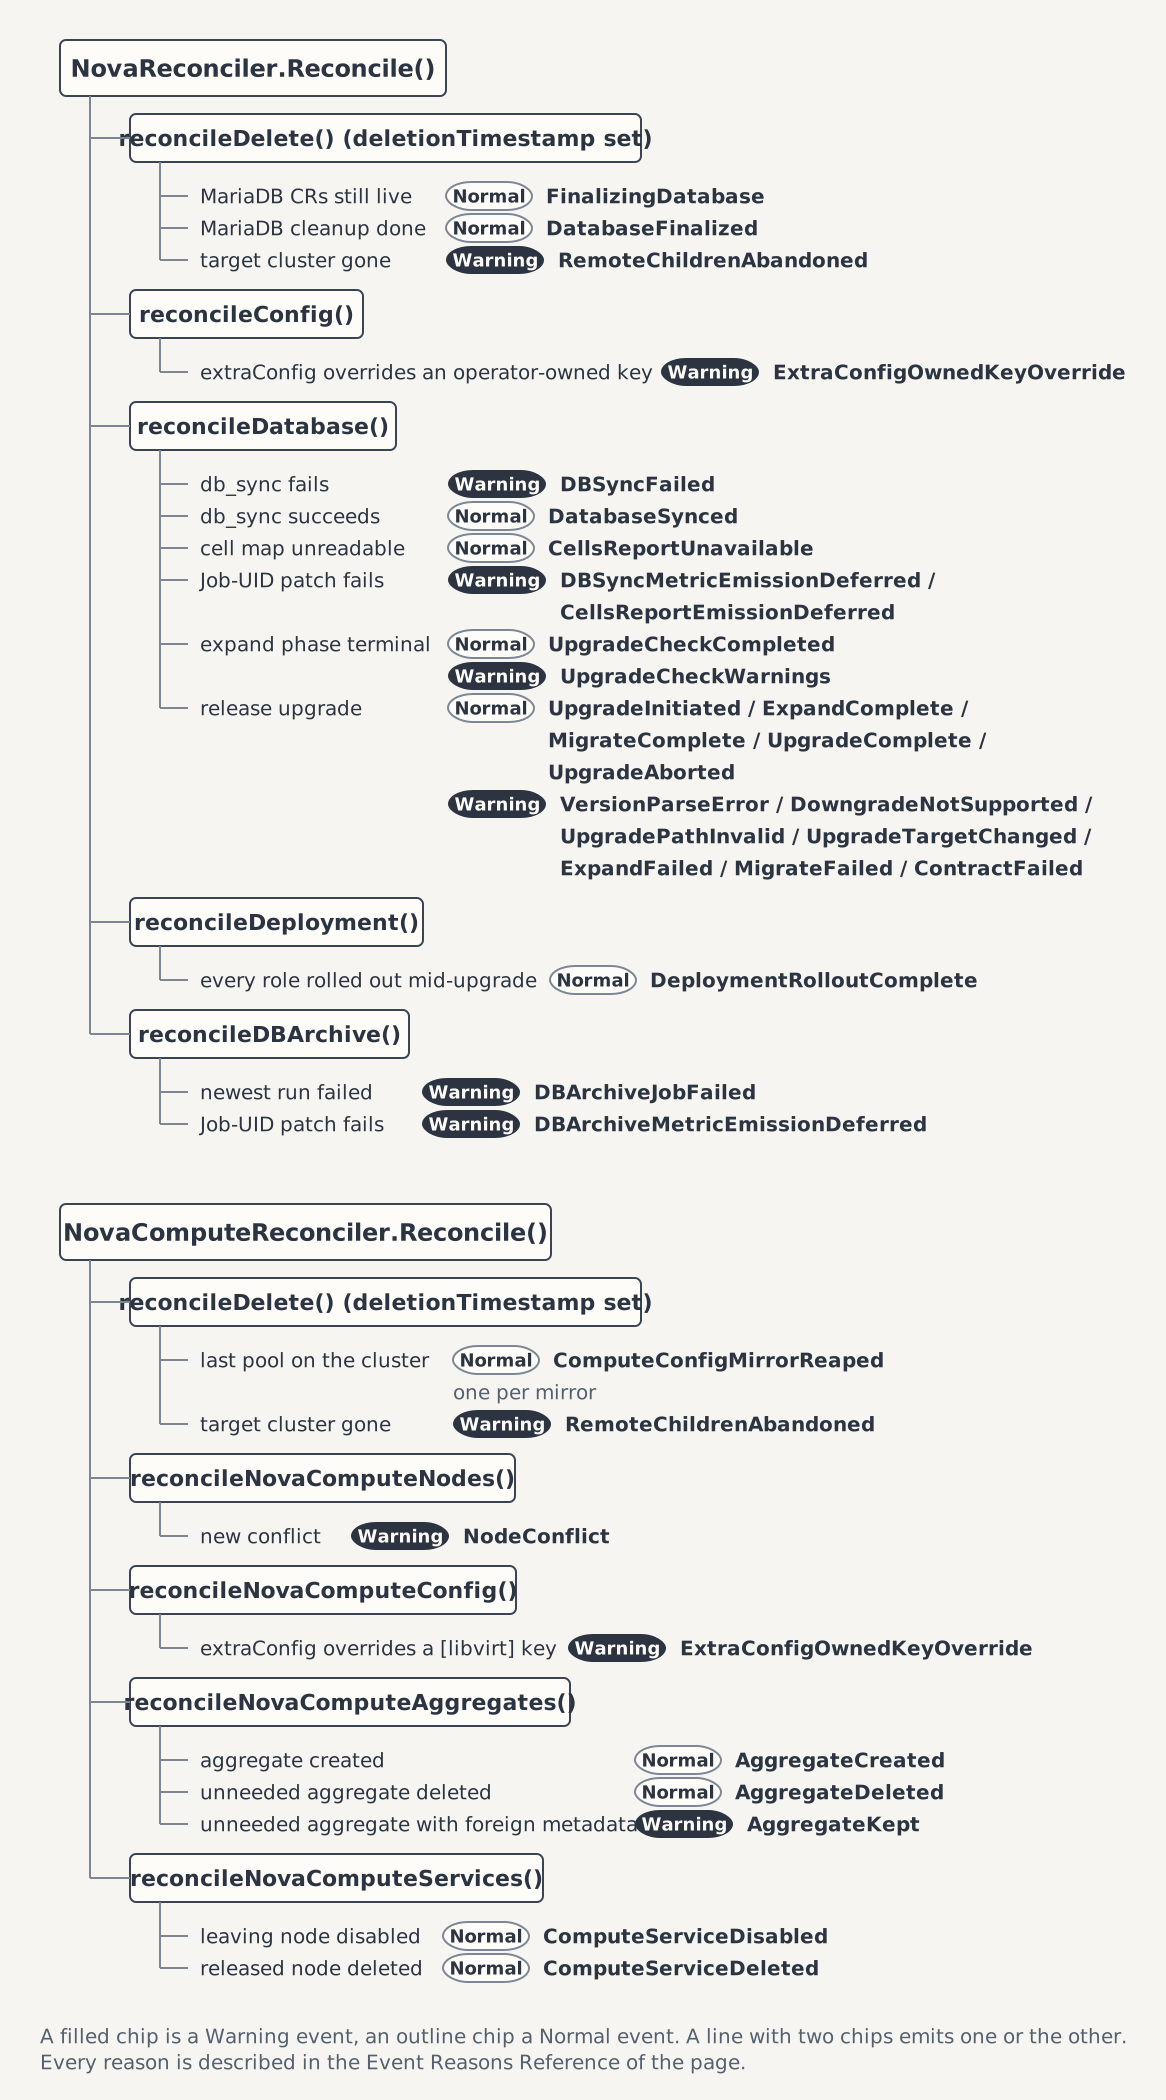
The figure draws which sub-reconciler emits which event, and on what. The Event Reasons Reference describes every reason.